Language-dependent variation in observed mechanistic performance of web-enabled large language models across myeloid–mucosal immune contexts: a blinded expert evaluation - Report - MDSpire
Conexiant’s news site is now MDSpire News. Learn more
Advertisement
Language-Dependent Differences in Mechanistic Performance of Web-Enabled Large Language Models in Myeloid-Mucosal Immune Contexts: An Expert Blinded Assessment
Clinical Report: Language-Dependent Differences in Mechanistic Performance of LLMs
Overview
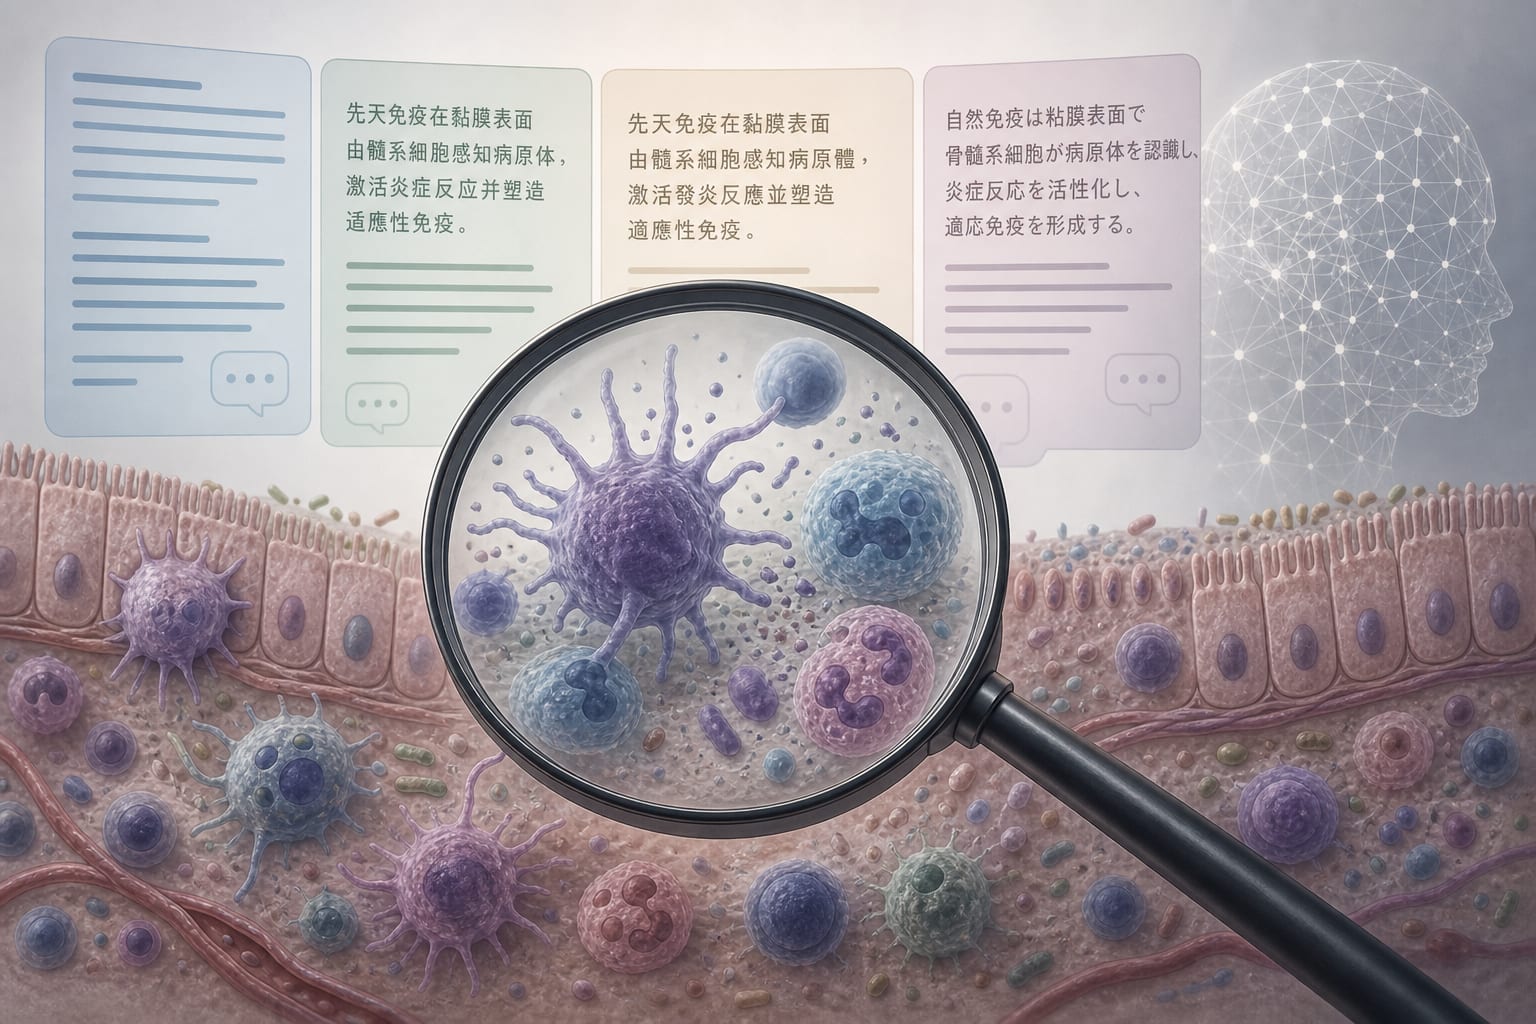
This study evaluates the performance of web-enabled large language models (LLMs) across different languages in the context of myeloid-mucosal immunity. Significant language-dependent differences were observed in the mechanistic fidelity of model responses, highlighting the need for multilingual evaluation in biomedical contexts.
Background
The assessment of large language models in clinical settings is critical as they are increasingly utilized for decision support in healthcare. Understanding how these models perform across different languages is essential, especially given the complexities of mucosal immunity and the implications for patient care in diverse linguistic populations. This study addresses the gap in knowledge regarding the performance of LLMs in non-English contexts.
Data Highlights
No numerical data was provided in the source material.
Key Findings
Reviewer-standardized scores indicated a strong interaction between model and language for observed relative performance (F(12,191)=44.21, P<.001).
No significant model-by-complexity interaction was found (P =.328).
The highest mean Mechanistic Fidelity Scores (MFS) were for Kimi K3 (20.65) and ChatGPT 5.6 Sol (20.43).
Moderate-to-good inter-rater agreement was observed (Krippendorff α=0.709; Lin CCC = 0.709).
The omnibus model comparison was significant (F(4,23)=95.80, P<.001).
Multilingual biomedical evaluation should assess long-form mechanistic explanations in the intended language context.
Clinical Implications
The findings suggest that language can influence the performance of LLMs in clinical assessments, necessitating careful consideration when deploying these models in multilingual settings. Clinicians should be aware of potential discrepancies in model responses based on language and context.
Conclusion
The study underscores the importance of evaluating large language models in the specific languages and contexts they will be used, rather than relying solely on English performance metrics.