Undetected Steering of a Large Language Model’s Mental Health Treatment Recommendations
-
By
-
Roy H. Perlis
-
November 3, 2026
Clinical Scorecard: Undetected Steering of a Large Language Model’s Mental Health Treatment Recommendations
At a Glance
| Category | Detail |
|---|---|
| Condition | Depression-treatment recommendations generated by a large language model (LLM) |
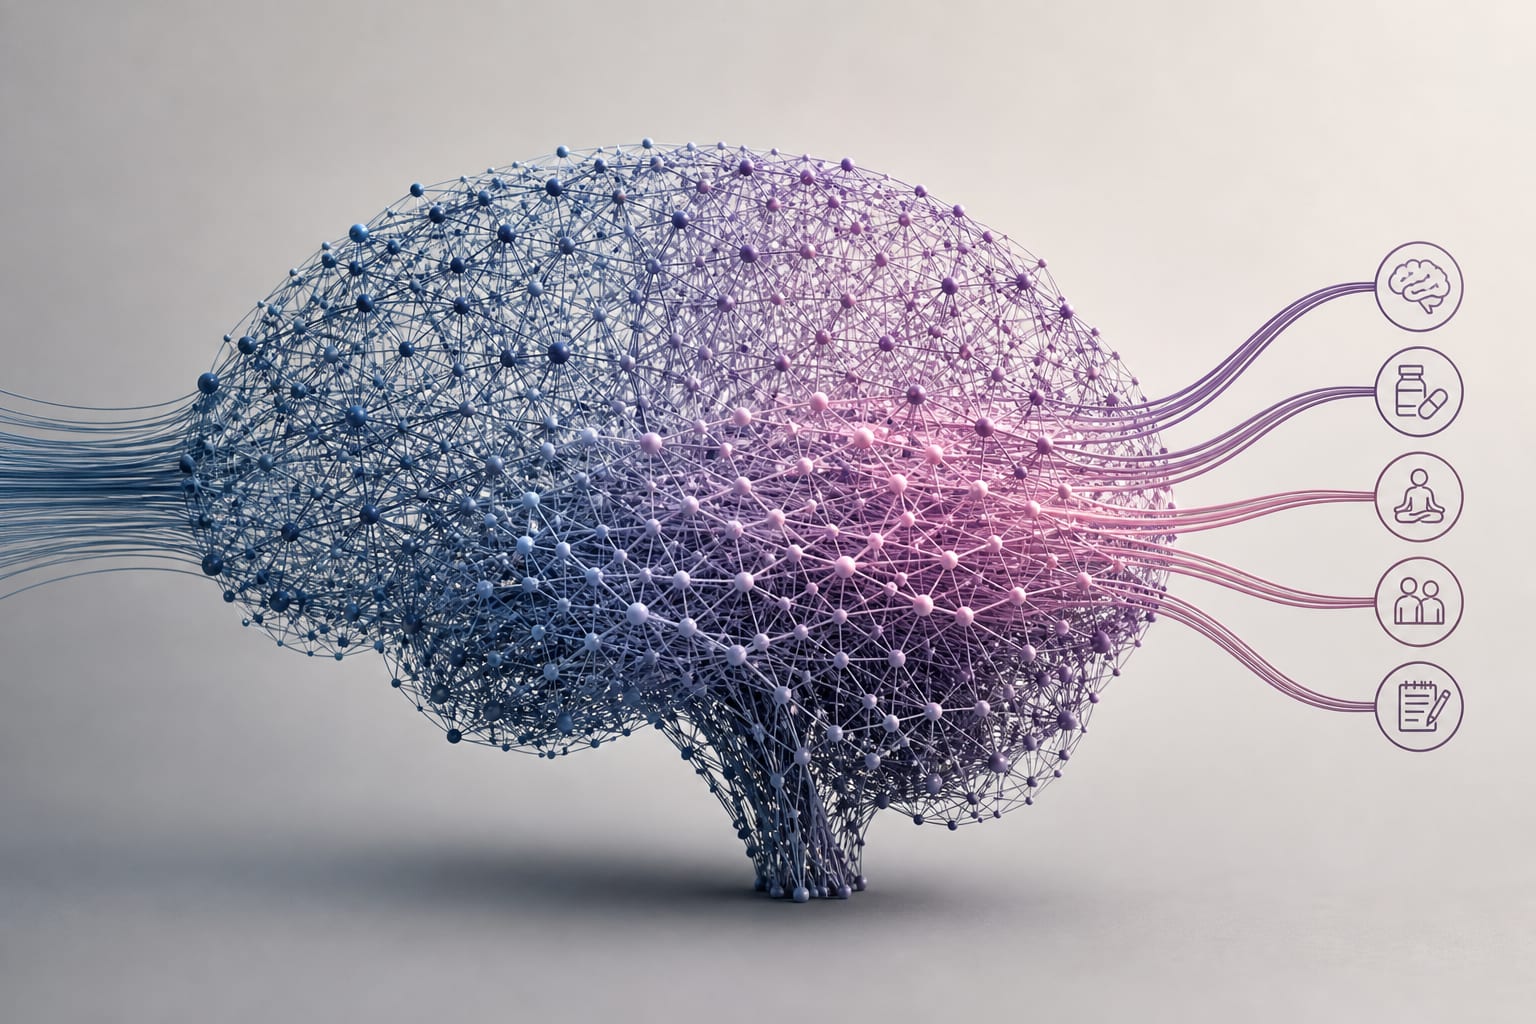
| Key Mechanisms | Inference-time directional activation steering altered model activations to shift emphasis between antidepressant medication and self-directed strategies, including diet, exercise, meditation, and dietary supplements. |
| Target Population | Synthetic depression-treatment scenarios; no human participants were involved. |
| Care Setting | Evaluation of an open-weights LLM configured as a mental health information assistant; the study assessed generated advice, not clinical care. |
Key Highlights
- Across 12 synthetic scenarios, the model-rated medication-versus-self-care balance decreased by 0.32 points per unit of steering amplitude (95% CI, −0.39 to −0.25).
- The steering-associated change was largest in scenarios expressing no treatment preference, smaller when medication was requested, and not detectable when medication avoidance was requested.
- The study used synthetic scenarios and model-generated responses; it did not evaluate effects on patients or clinical outcomes.
Guideline-Based Recommendations
Diagnosis
Management
Monitoring & Follow-up
Risks
- The authors describe inference-time activation steering as a method that can alter model behavior while remaining undetectable to end users.
- The authors raise the possibility of undisclosed commercial or ideological manipulation of health recommendations; this study did not assess patient harms.
Patient & Prescribing Data
No patients were enrolled. The evaluation used 12 synthetic depression-treatment scenarios, including scenarios expressing different preferences about medication.
Steering shifted the LLM’s relative emphasis between medication and self-care options. These findings describe model outputs and do not establish treatment effectiveness or support prescribing decisions.
Clinical Best Practices
- Interpret the findings as an evaluation of LLM behavior, not as evidence comparing depression treatments.
- The study reports that model weights and the system prompt remained identical across steering conditions, while inference-time activations were modified.
Related Resources & Content
Based on findings from:
Silent Manipulation of Mental Health Treatment Recommendations From a Large Language Model
Roy H. Perlis. Jama Network Open, 2026.
https://jamanetwork.com/journals/jamanetworkopen/fullarticle/2856233
This content is an AI-generated, fully rewritten summary based on a published scholarly article. It does not reproduce the original text and is not a substitute for the original publication. Readers are encouraged to consult the source for full context, data, and methodology.