-
1
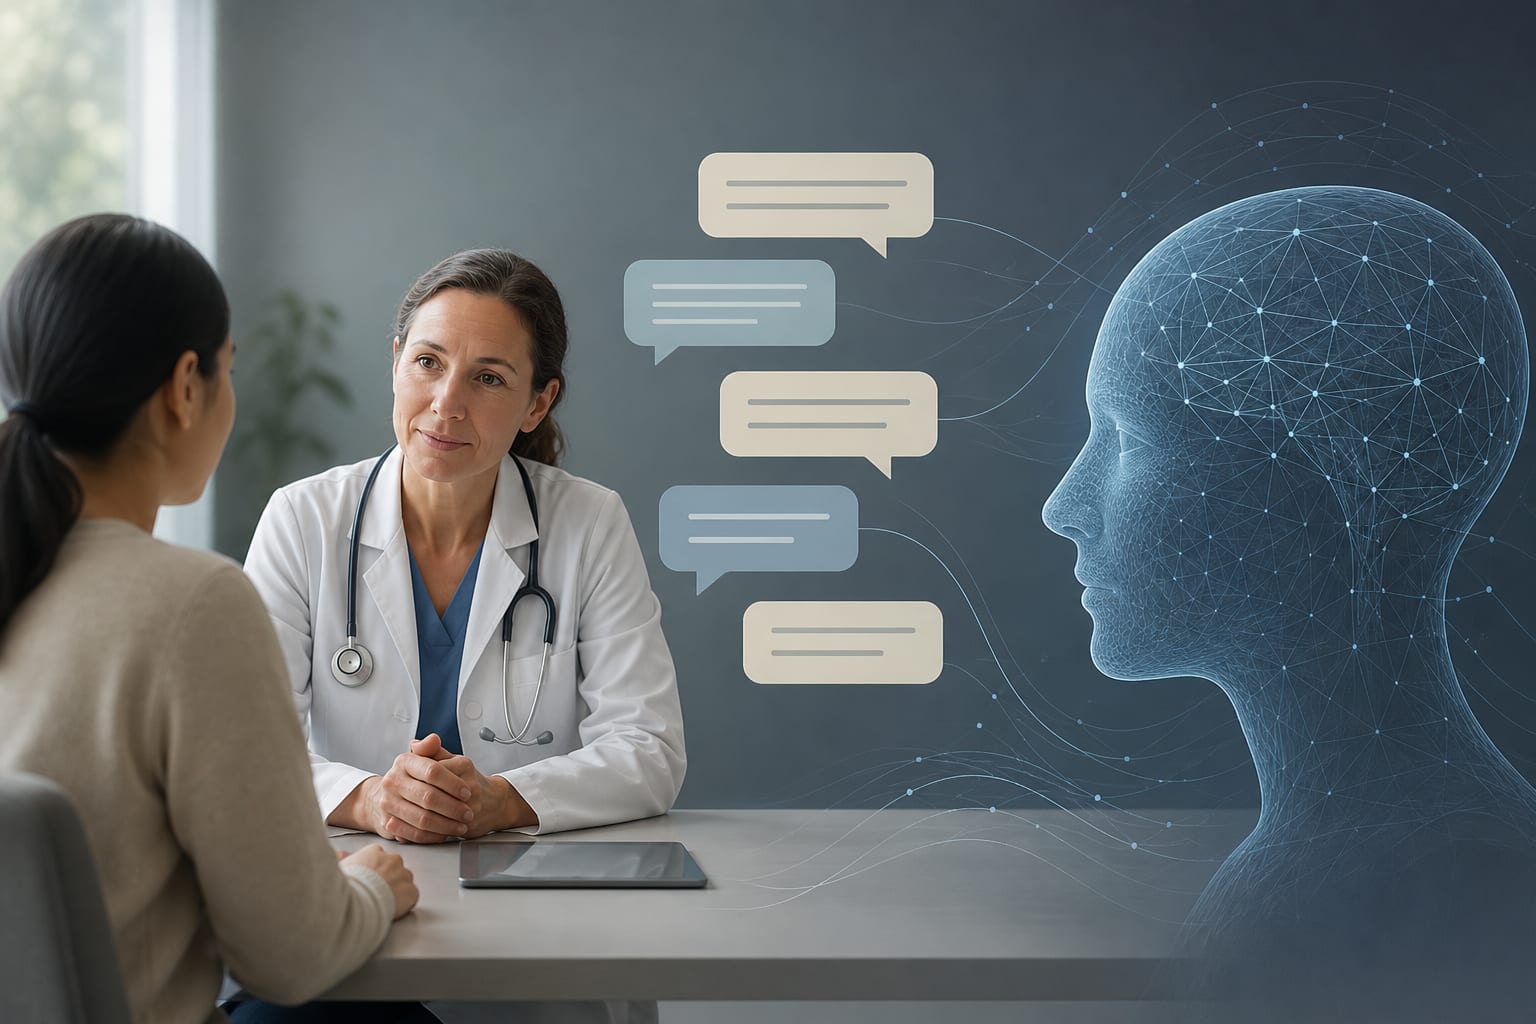
Across 10 studies, AI-generated responses received higher empathy ratings than physician responses (standardized mean difference, 1.02; 95% CI, 0.44-1.60; odds ratio, 5.5).
-
2
The review found substantial heterogeneity (I²=73%) and no randomized trials, longitudinal data, or direct measurement of trust; empathy did not differ in the sole disease-specific study.
-
3
Written-response ratings do not capture empathy in clinical dialogue, including how clinicians address ambiguity, respond to emotion, and adapt to changing patient information.
-
4
In one study, reviewers identified potentially harmful AI responses that patients rated highly and could not distinguish, showing that convincing language can accompany inaccuracy.
-
5
The authors call for risk-proportionate evaluation, including local validation, longitudinal auditing, readability and subgroup assessments, and workflow monitoring before deployment.